Built for large-scale AI training and inference, ExaStor delivers data to GPUs at high speed and with consistent performance, maximizing AI workload performance and efficiency.
Distributed metadata and small-file optimization reduce bottlenecks in large-scale file environments.
Flexible Scalability
Start with a single node and scale capacity and throughput together as data demands grow.
Optimized Data Placement
Leverages storage tiers based on data characteristics and access patterns to optimize performance and cost.
Enterprise Data Protection
High availability, snapshots, remote replication, and data integrity verification protect AI data and ensure service continuity.
0GiB/s
Seq. Read
0kIOPS
Find
0%
CPU Usage Reduction (GDS)
0X
Data Reduction
Beyond Performance, Toward an Enterprise AI Data Platform
High-performance
High Availability
Scalability and Efficiency
Streamlined Management
High-performance Parallel File System
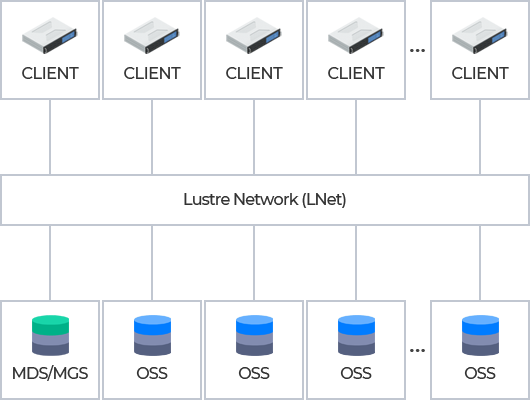
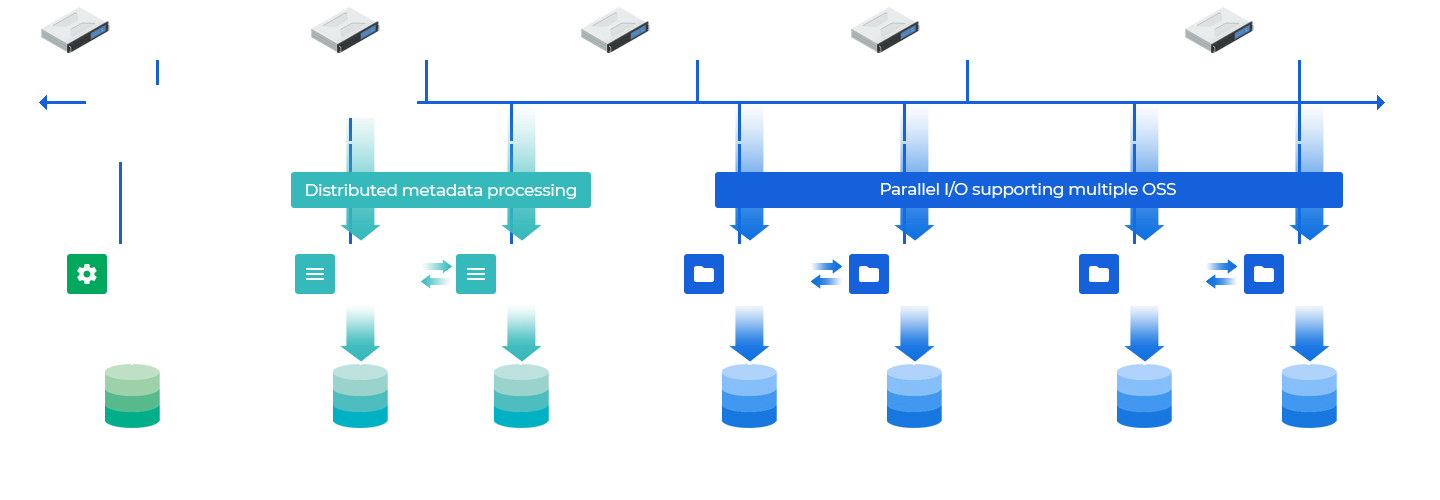
Allows parallel data access through Luster parallel file system, with high-speed file sharing and petabyte-level scalability through its parallel I/O architecture. Files are distributed and stored in objects across the cluster through global namespace.
NVIDIA® GPUDirect® Storage Support
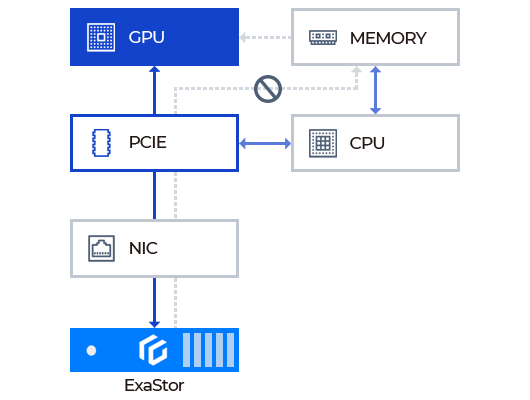
Provides a storage interface to accelerate GPU applications, minimizing CPU and memory load. Maximizes GPU performance by providing a distributed file system IO driver module for applications running on GPGPU.
Flash-based Level 2 Cache
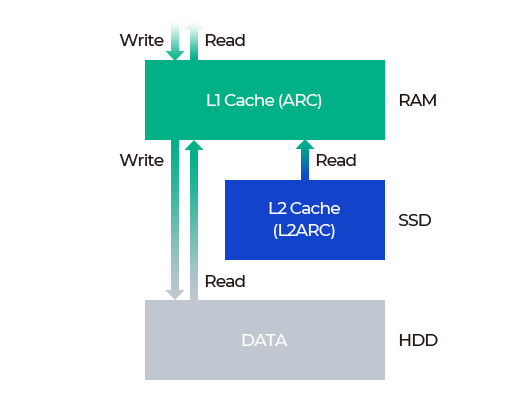
Can leverage SSD drives as secondary read cache, extending the main memory cache. When the main memory is full, the system can perform read request on the allocated cache drive, instead of using slower hard drives.
High-Speed Checkpoint Writes
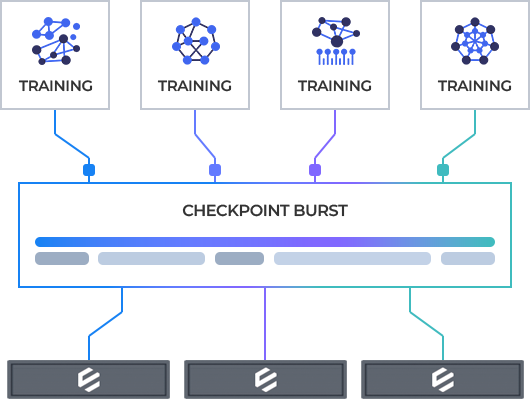
ExaStor distributes large-scale checkpoint data across multiple storage nodes for parallel processing and leverages metadata caching to reduce checkpoint write time.
Faster checkpointing enables more frequent checkpoints, reducing the amount of training that must be repeated after a failure and improving training continuity.
Hardware Redundancy
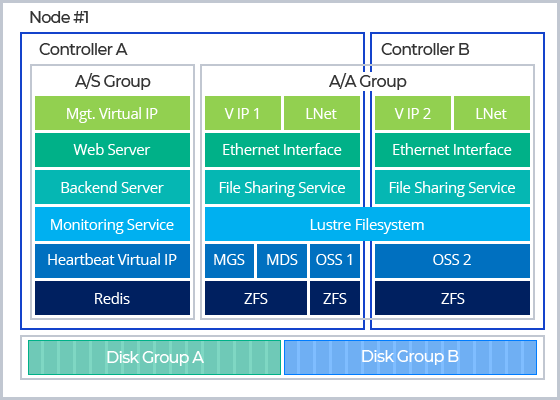
Redundancy based on dual controllers ensures service continuity through automatic failover in the event of a controller failure. This architecture effectively eliminates the risk of split-brain scenarios during data synchronization, ensuring data integrity and reliability. (※ dual controller model only)
High Availability Architecture
Ensure uninterrupted services by active-active storage redundancy architecture.
Minimize interconnectivity between resources as well as the complexity of active-active configuration to provide instant recovery through partial failover.
Multi-Rail Network
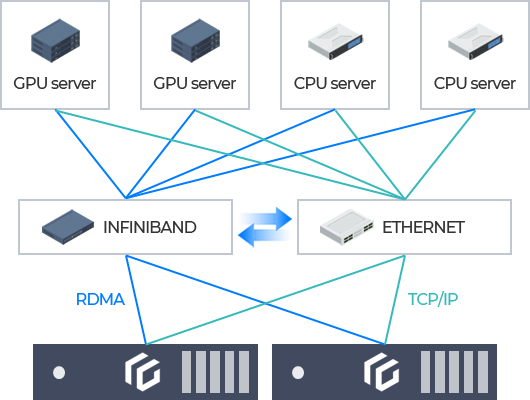
Supports parallel network I/O with multi-rail configuration utilizing both TCP/IP and RDMA network. Network traffics are automatically distributed through load balancing to prevent bottleneck while optimizing the overall network performance.
Flexa Snapshot Manager
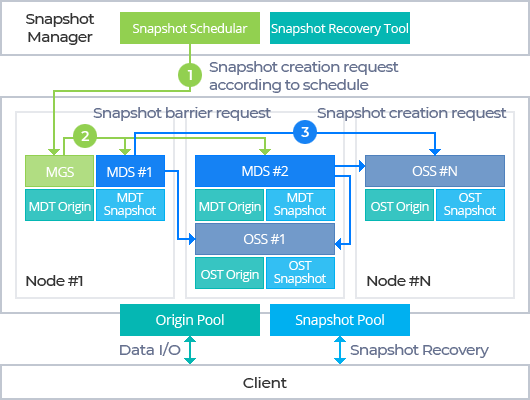
Leverage the power of the Global Write Barrier of Flexa Snapshot Manager to take instant snapshots across all storage clusters without any system downtime. Snapshots are swiftly generated through copy-on-write by capturing only the changes, operating deep within the file system layer to ensure minimal impact on metadata performance.
Delta Log Sync
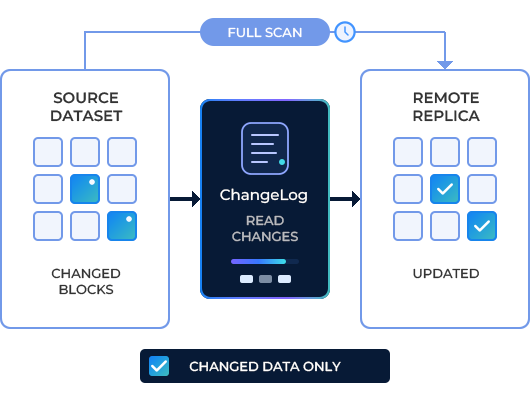
Synchronizes only modified data based on the metadata server’s Change Log. By eliminating the need to rescan the entire file system, ExaStor enables fast and efficient remote replication of large-scale training datasets.
Tiering
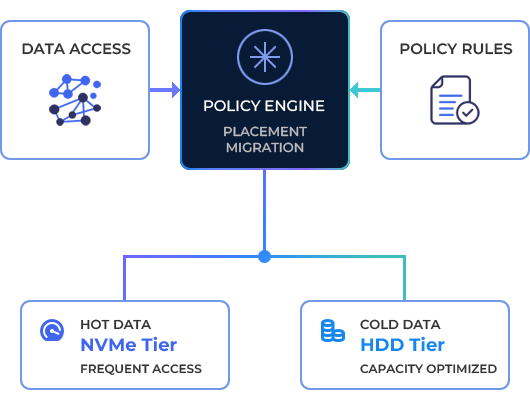
Integrates storage tiers with different performance characteristics, including NVMe SSDs, SSDs, and HDDs, into a single file system and automatically tiers data through policy-based Smart Tiering.
Frequently accessed data is kept on high-performance tiers for faster access, while less frequently used data is automatically moved to high-capacity tiers, enabling more efficient utilization of storage resources.
Storage Space Optimization
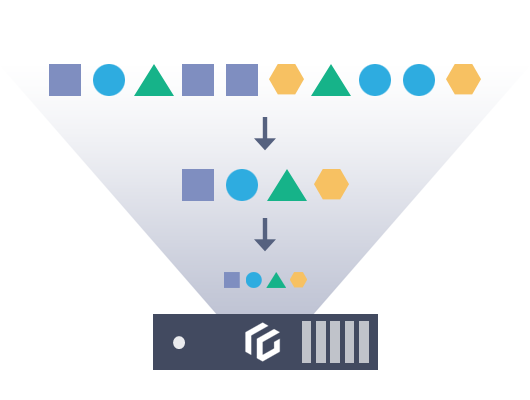
Achieve optimal storage efficiency with real-time data compression, which reduces I/O bandwidth and maximizes storage space utilization. This advanced technology also delivers integrity checks on compressed data, ensuring the detection of data corruption and maintaining data integrity.
Scale-out Architecture
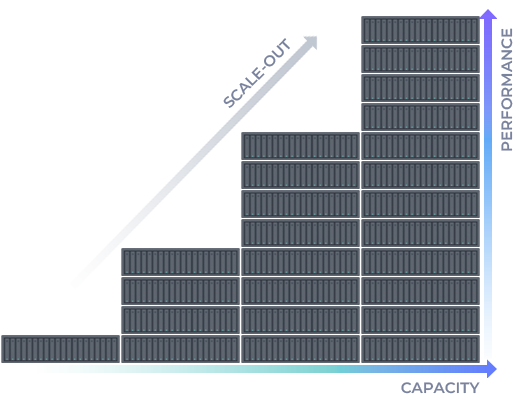
Effortlessly scale your storage capacity by dynamically adding nodes online. You can achieve massive storage space in petabyte-level in a single system, while having linear performance boosts through parallel scaling. This approach not only minimizes the scale of initial adoption but also ensures cost-effective storage management tailored to your business needs and data growth.
Dynamic Storage Scaling
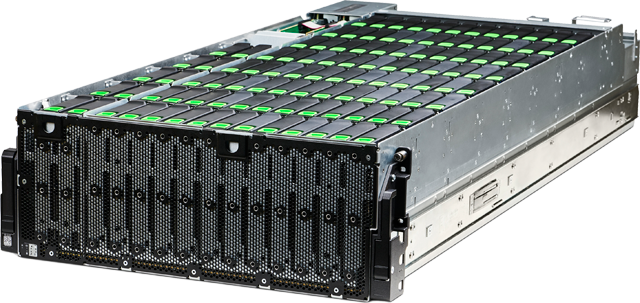
Optimize your high-capacity, high-density storage with a cutting-edge storage enclosure that supports up to 108 SAS drives in a compact 4U form factor. When scaling up with the E484 model, you can install up to 408 disks, configuring a massive 8.16PB of physical capacity. This scalable architecture ensures your storage infrastructure can grow seamlessly with your data demands.
Advanced Performance Monitoring
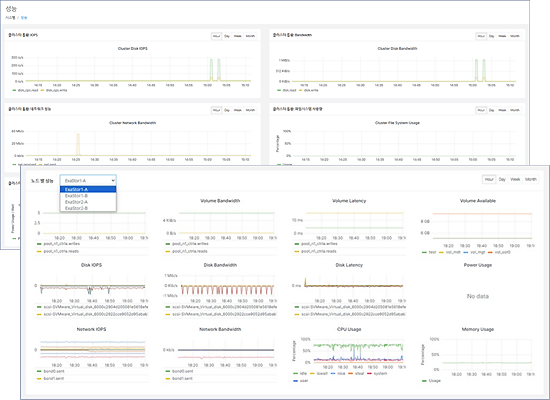
With our dedicated management software, you can effortlessly track the IOPS and bandwidth for clusters and local volumes. It provides real-time monitoring of network I/O performance for every controller, file system usage, power consumption, and CPU/memory utilization per controller, ensuring visibility of your system’s performance metrics.
Comprehensive System Monitoring
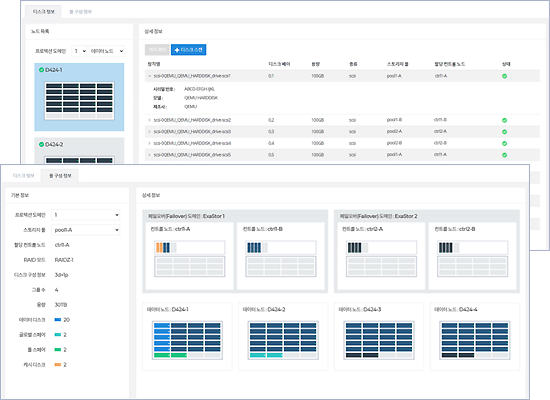
Monitor system usage and availability across clusters and local volumes, including NFS, CIFS, and file system clients. Our dedicated management software enables real-time tracking of disk health and location within the system, ensuring efficient and effective management.
Container Integration
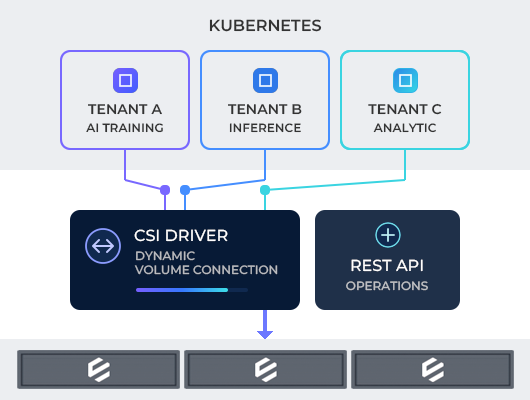
ExaStor seamlessly integrates storage volumes with Kubernetes environments through its CSI Driver. Multi-tenancy and QoS enable efficient resource management across workloads, while REST APIs support integration with external management systems and automated operations.
Multi-Protocol Support
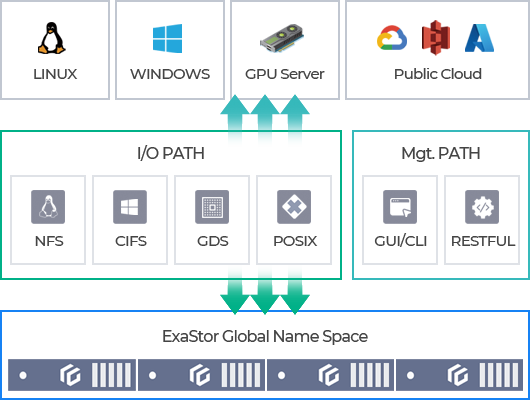
ExaStor supports a wide range of protocols, including NFS, CIFS, GPUDirect Storage, POSIX-compliant interfaces, and RESTful APIs, ensuring that heterogeneous users and applications can seamlessly access its global namespace.
System Architecture
System Configuration
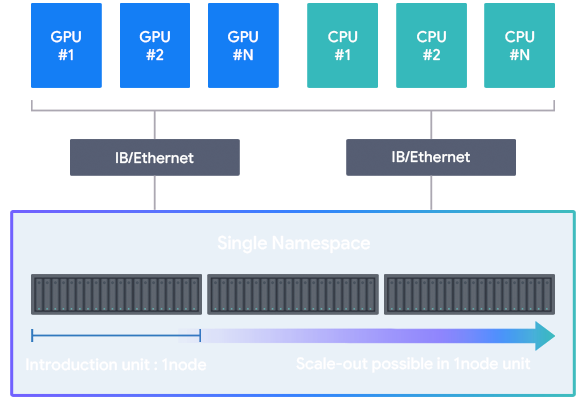
DC/SC Integrated Architecture
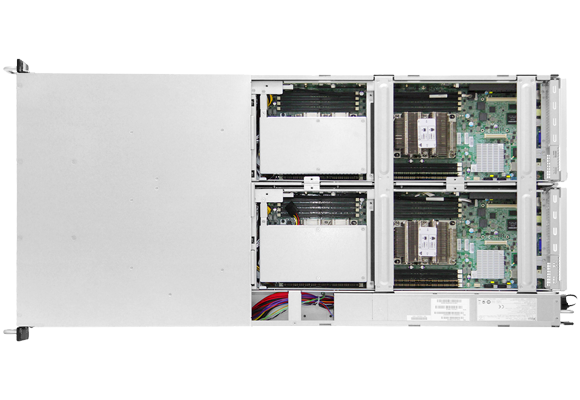
High availability with an Active-Active HA configuration within a single chassis (*DC models only)
Delivers up to 160 GB/s per node with NVMe SSDs
Start with a single node and scale flexibly one node at a time
Supports NVMe all-flash or SAS hybrid configurations
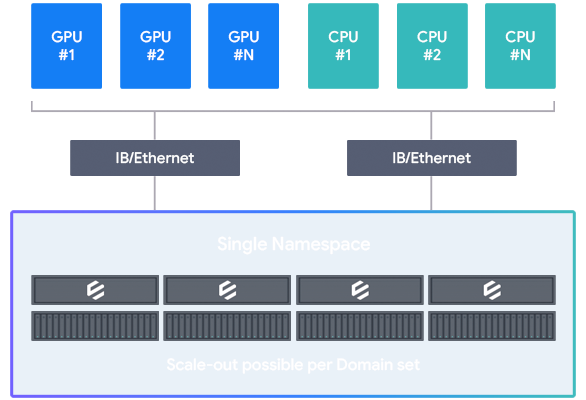
SC Scale-Out Architecture
Disaggregated architecture with separate control and data nodes
Supports HA configuration with four control nodes per domain
Scales incrementally by domain
Separates the service network from the dedicated storage network
Supports SAS/SATA hybrid configurations
Are you interested in our products? Get in touch with Gluesys.